Lovable SEO: Is It Good for Search, and How to Check Your App
Is Lovable good for SEO? As of November 6, 2026: which apps are server-rendered, what Lovable's built-in SEO & AI search review checks and misses, custom domains, and a 15-minute test for your own URL.
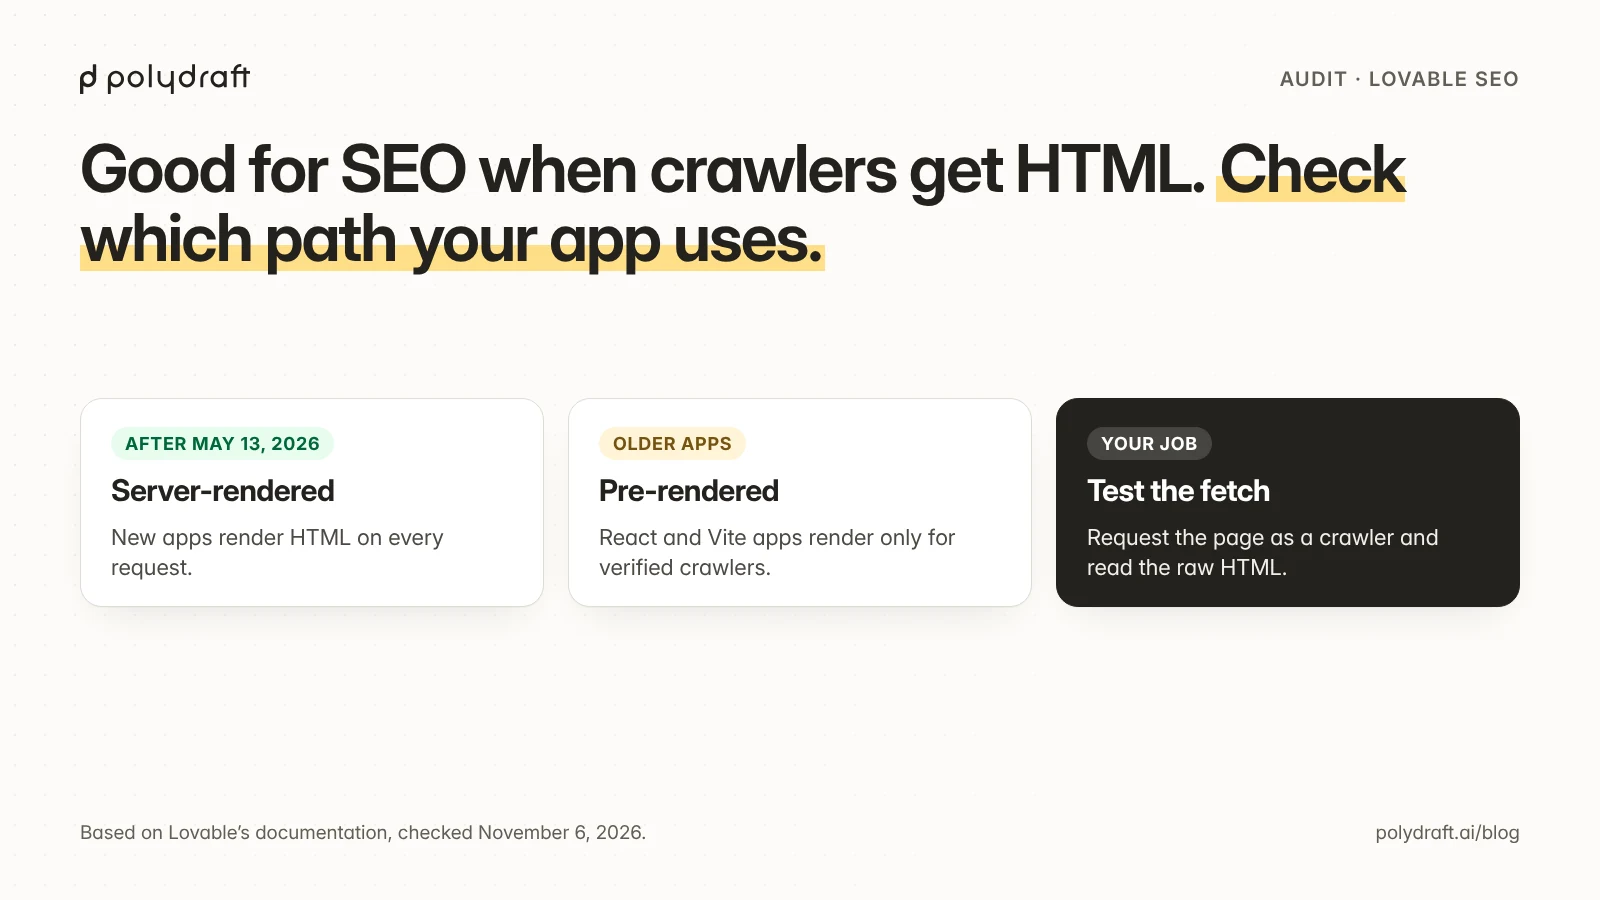
Lovable is good for SEO as long as your pages reach crawlers as HTML, and as of November 6, 2026, Lovable's documentation says they do. Apps created on or after May 13, 2026 (June 22, 2026 on Enterprise plans) are server-rendered for every request. Older React and Vite apps are pre-rendered only for verified crawlers. Lovable also has a built-in SEO & AI search review that checks and fixes the basics. Rankings still depend on your content, links and competition.
Updated November 6, 2026: added which Lovable apps are server-rendered (those created on or after May 13, 2026), sections on Lovable's built-in SEO & AI search review and on custom domains, and test commands.
This guide shows how to tell which rendering path your app uses, what Lovable's own review covers and what it leaves to you, and a 15-minute test you can run on your own URL. It relies on Lovable's documentation, read on November 6, 2026. We didn't build test projects for it, so every result about your app comes from running the test yourself.
Key takeaways
- Creation date decides rendering. Lovable apps created on or after May 13, 2026 (June 22, 2026 on Enterprise) use TanStack Start with server-side rendering. Older React and Vite apps serve pre-rendered pages to verified crawlers and the client-side app to everyone else.
- Older apps can upgrade. Lovable documents an in-place upgrade to TanStack Start. It uses credits and takes effect when you publish again.
- Run Lovable's review first. The SEO & AI search review checks the sitemap, robots.txt, metadata, structured data, page structure, alt text, canonicals, indexing and AI readiness, and can fix most findings. It doesn't check page speed.
- Then test from outside. The review reports on your project. The test below shows what a browser, a plain client and an AI assistant actually receive at your URL.
- Use a custom domain. Search presence builds on a domain you own. Custom domains need a paid plan.
Is Lovable good for SEO?
Yes, for search engines and the major AI search crawlers: Lovable's documentation says published Lovable apps return readable HTML to both, on both of its stacks, and that neither stack needs an external pre-rendering service. The difference between the stacks shows up with everyone else. A server-rendered app gives every request the same HTML. An older app gives rendered HTML only to crawlers Lovable has verified. This is what each kind of request receives, according to Lovable's SEO and hosting documentation as of November 6, 2026:
| Who is asking | App created on or after May 13, 2026 (TanStack Start) | Older React + Vite app |
|---|---|---|
| A person in a browser | Fully rendered HTML | The single-page app: the browser builds the page with JavaScript |
| A verified crawler: Google and Bing, the AI search crawlers of ChatGPT, Perplexity, Claude and Gemini, social-preview bots, verified SEO tools | Fully rendered HTML | A copy rendered on request. Content that loads late may be missing |
| An unverified bot, a link checker, a third-party SEO scanner that isn't verified | Fully rendered HTML | The regular single-page app, which can look nearly empty |
| Any client that asks for Markdown | A Markdown version of the page | A Markdown version of the page |
Lovable's hosting page adds a warning worth knowing before you trust any outside audit tool: on older apps, third-party SEO scanners aren't verified crawlers, so they may report your pages as empty even though Google, social platforms and AI search engines receive the full content. Lovable's FAQ is just as clear that rendering is only the start. Ranking still depends on content quality, search intent, backlinks, competition and performance.
Which rendering path does my Lovable app use?
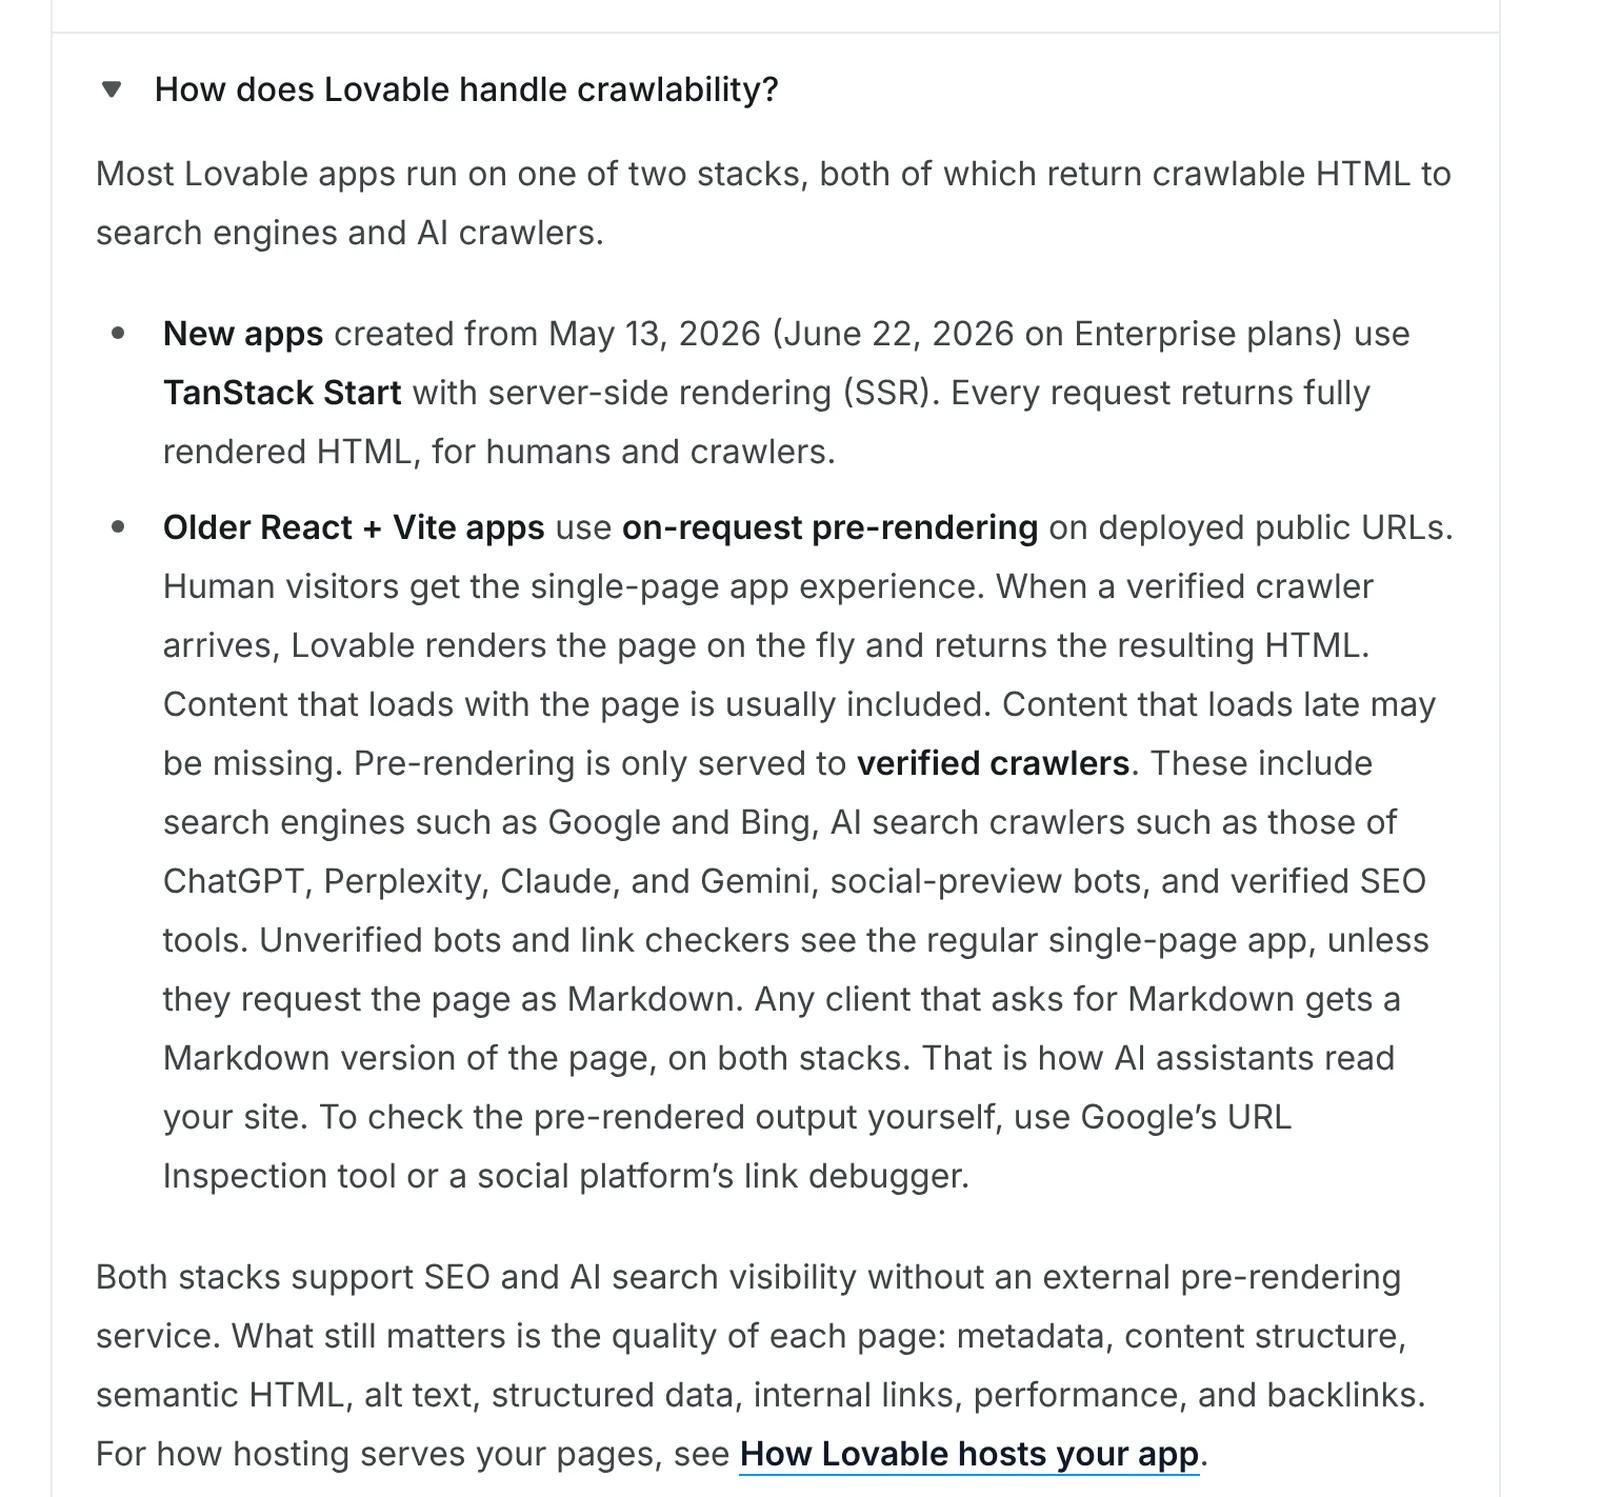
Your Lovable app's rendering path depends on when the project was created. Lovable made TanStack Start, with server-side rendering, the default for new projects on May 13, 2026, and for new Enterprise projects on June 22, 2026. Projects created before those dates are on the older React and Vite stack unless someone upgraded them.
- Not sure? Lovable's upgrade guide suggests asking Lovable in the project chat: "What stack is this project on?" Steps 1 and 2 of the test below also tell you, from the outside.
- On the older stack? Lovable documents an in-place upgrade to TanStack Start, from the project chat or project settings. As of November 6, 2026, its guide says most upgrades cost 10 to 35 credits, any editor can start one on any plan, the published site keeps serving the old version until you publish again, and you can revert from version history.
- Staying on the older stack? That's a documented choice, not a broken setup. Pre-rendering continues automatically for verified crawlers. Decide whether tools outside that list matter to you.
What Lovable's own SEO review checks (and what it doesn't)
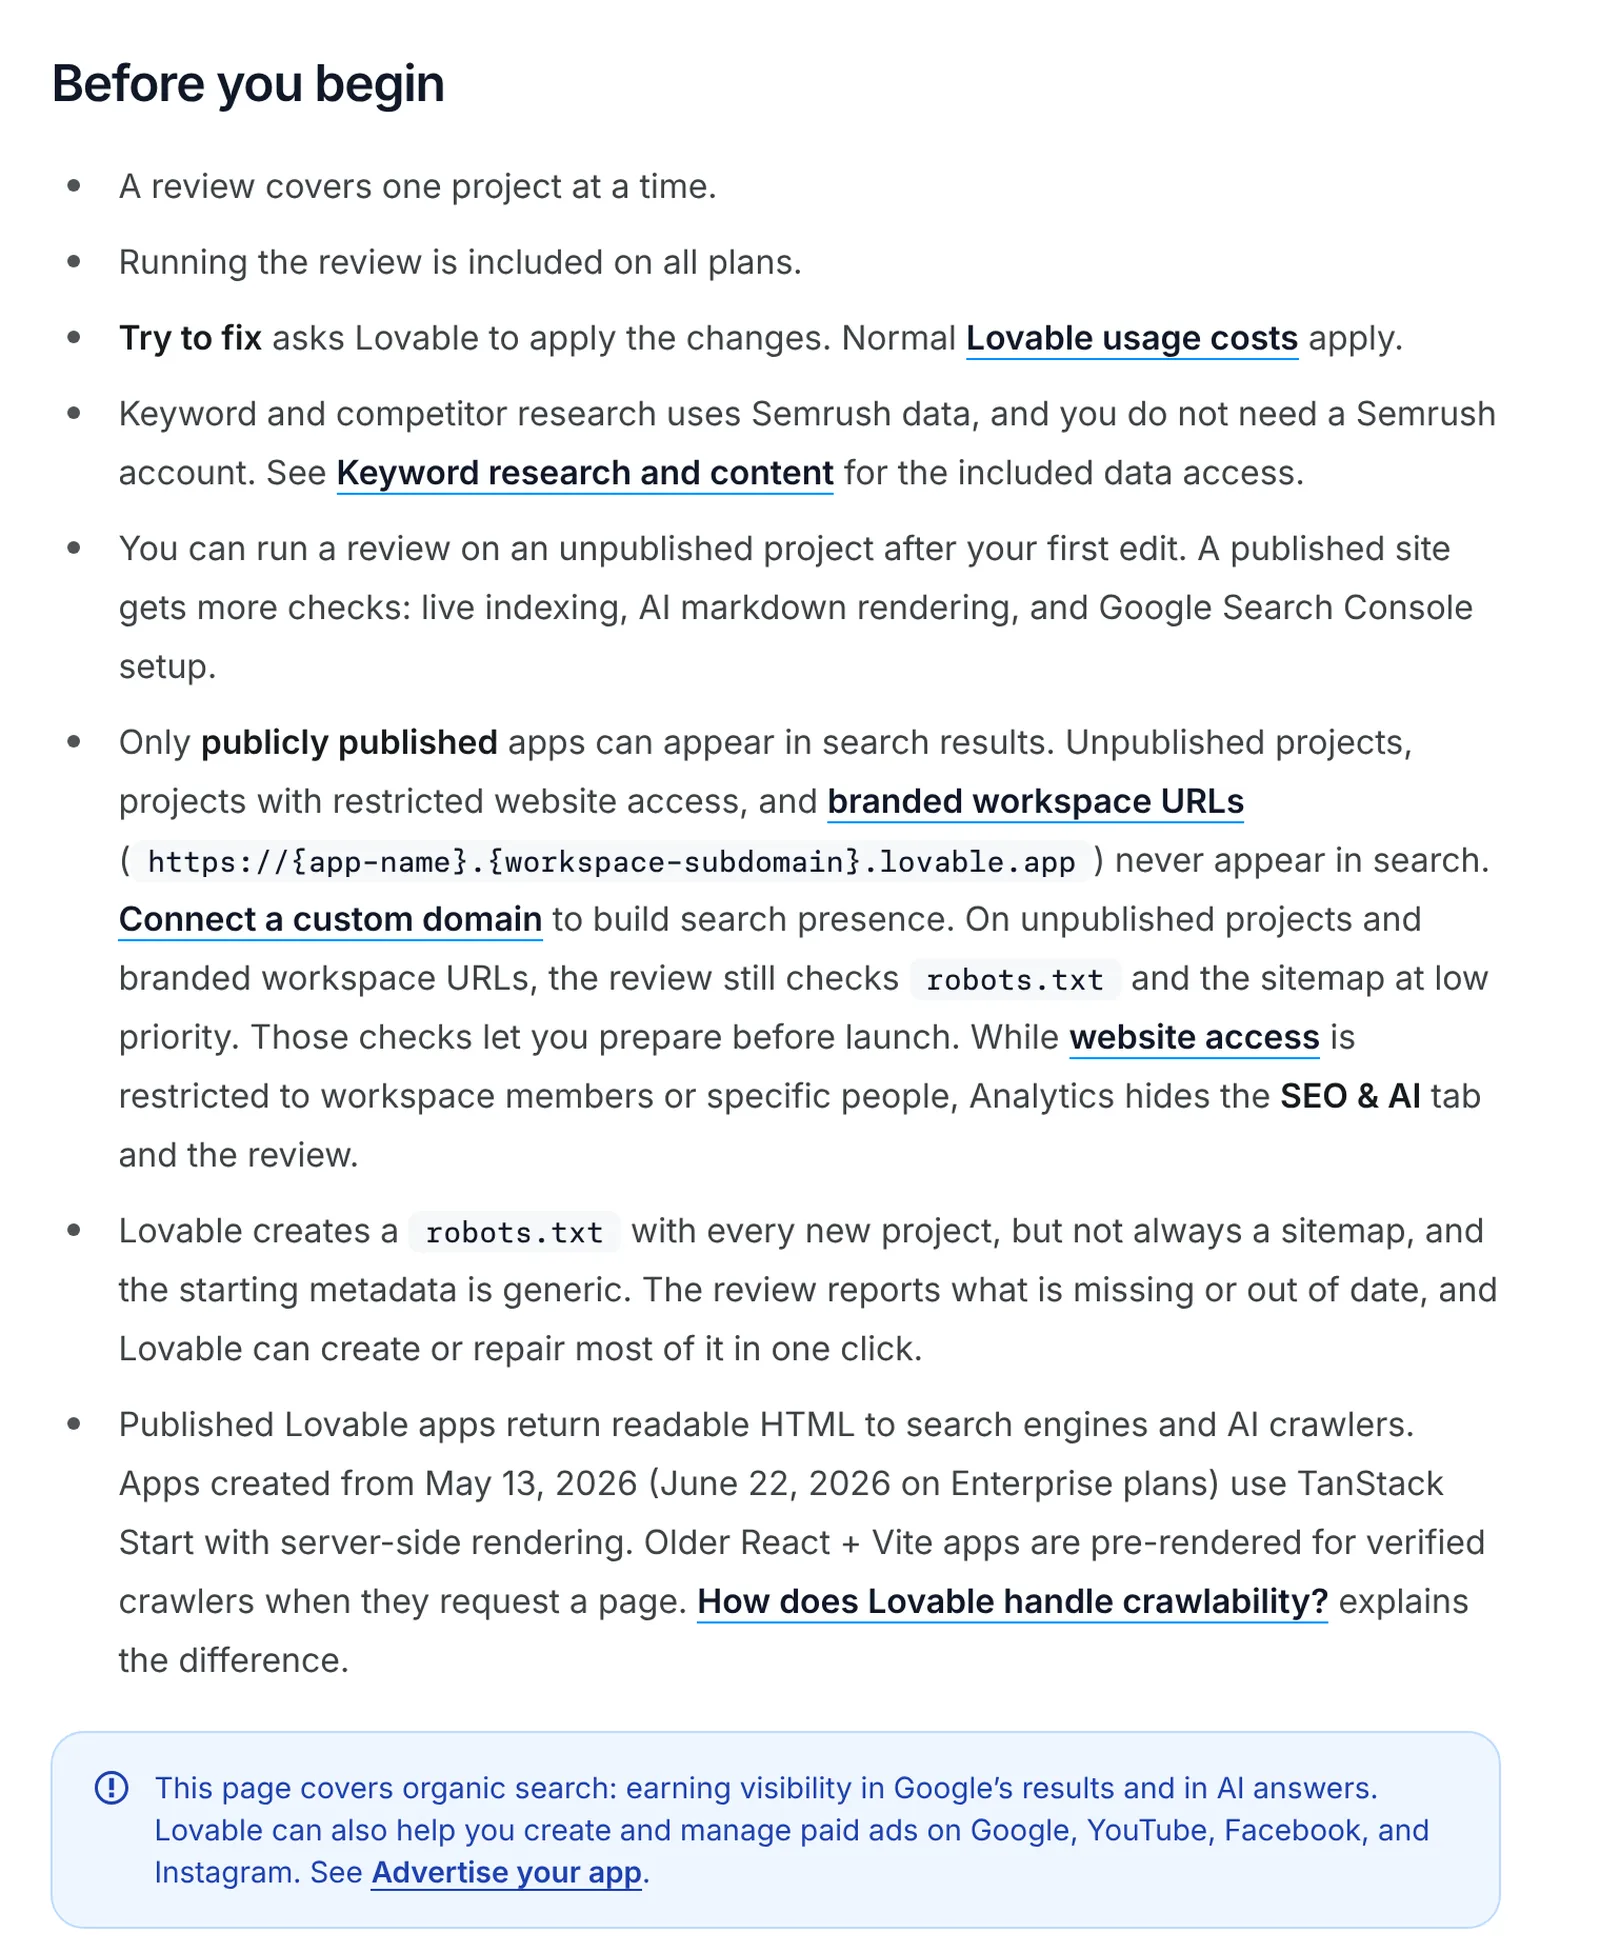
Lovable includes an SEO & AI search review for each project, on the SEO & AI tab of Analytics (More → Analytics in the project toolbar). As of November 6, 2026, Lovable's documentation says it checks the sitemap, robots.txt, metadata, structured data, page structure, alt text, canonical tags, indexing and AI readiness, explains each finding, and can fix most of them with Try to fix. Running the review is included on all plans. Fixes use normal Lovable credits.
What else the documentation says the SEO & AI tab does:
- Checks in layers. Code checks run on every project. Preview checks cover whether the home page loads, robots.txt and sitemap.xml. Published checks run only on a live public site and cover indexing and whether AI crawlers get a Markdown version.
- Google Search Console. Connect Search Console from the Google searches card or in chat. Lovable can then add Google's verification tag to your app's HTML, verify the site and submit your sitemap in chat. It asks you to approve a publish first if the tag isn't live yet. The card shows clicks, impressions and the searches that brought people in.
- Keyword and competitor research. Ask in chat. Lovable answers with Semrush data and names Semrush as the source, without a Semrush account. Its documentation says that data has no additional fees through November 30, 2026; normal credits still apply.
- Suggestions. Get more search traffic recommends one next step for a published site, such as a keyword to write for or a page to improve.
- Only when you run it. The review doesn't rerun on its own when you publish. Scan again after changes or fixes.
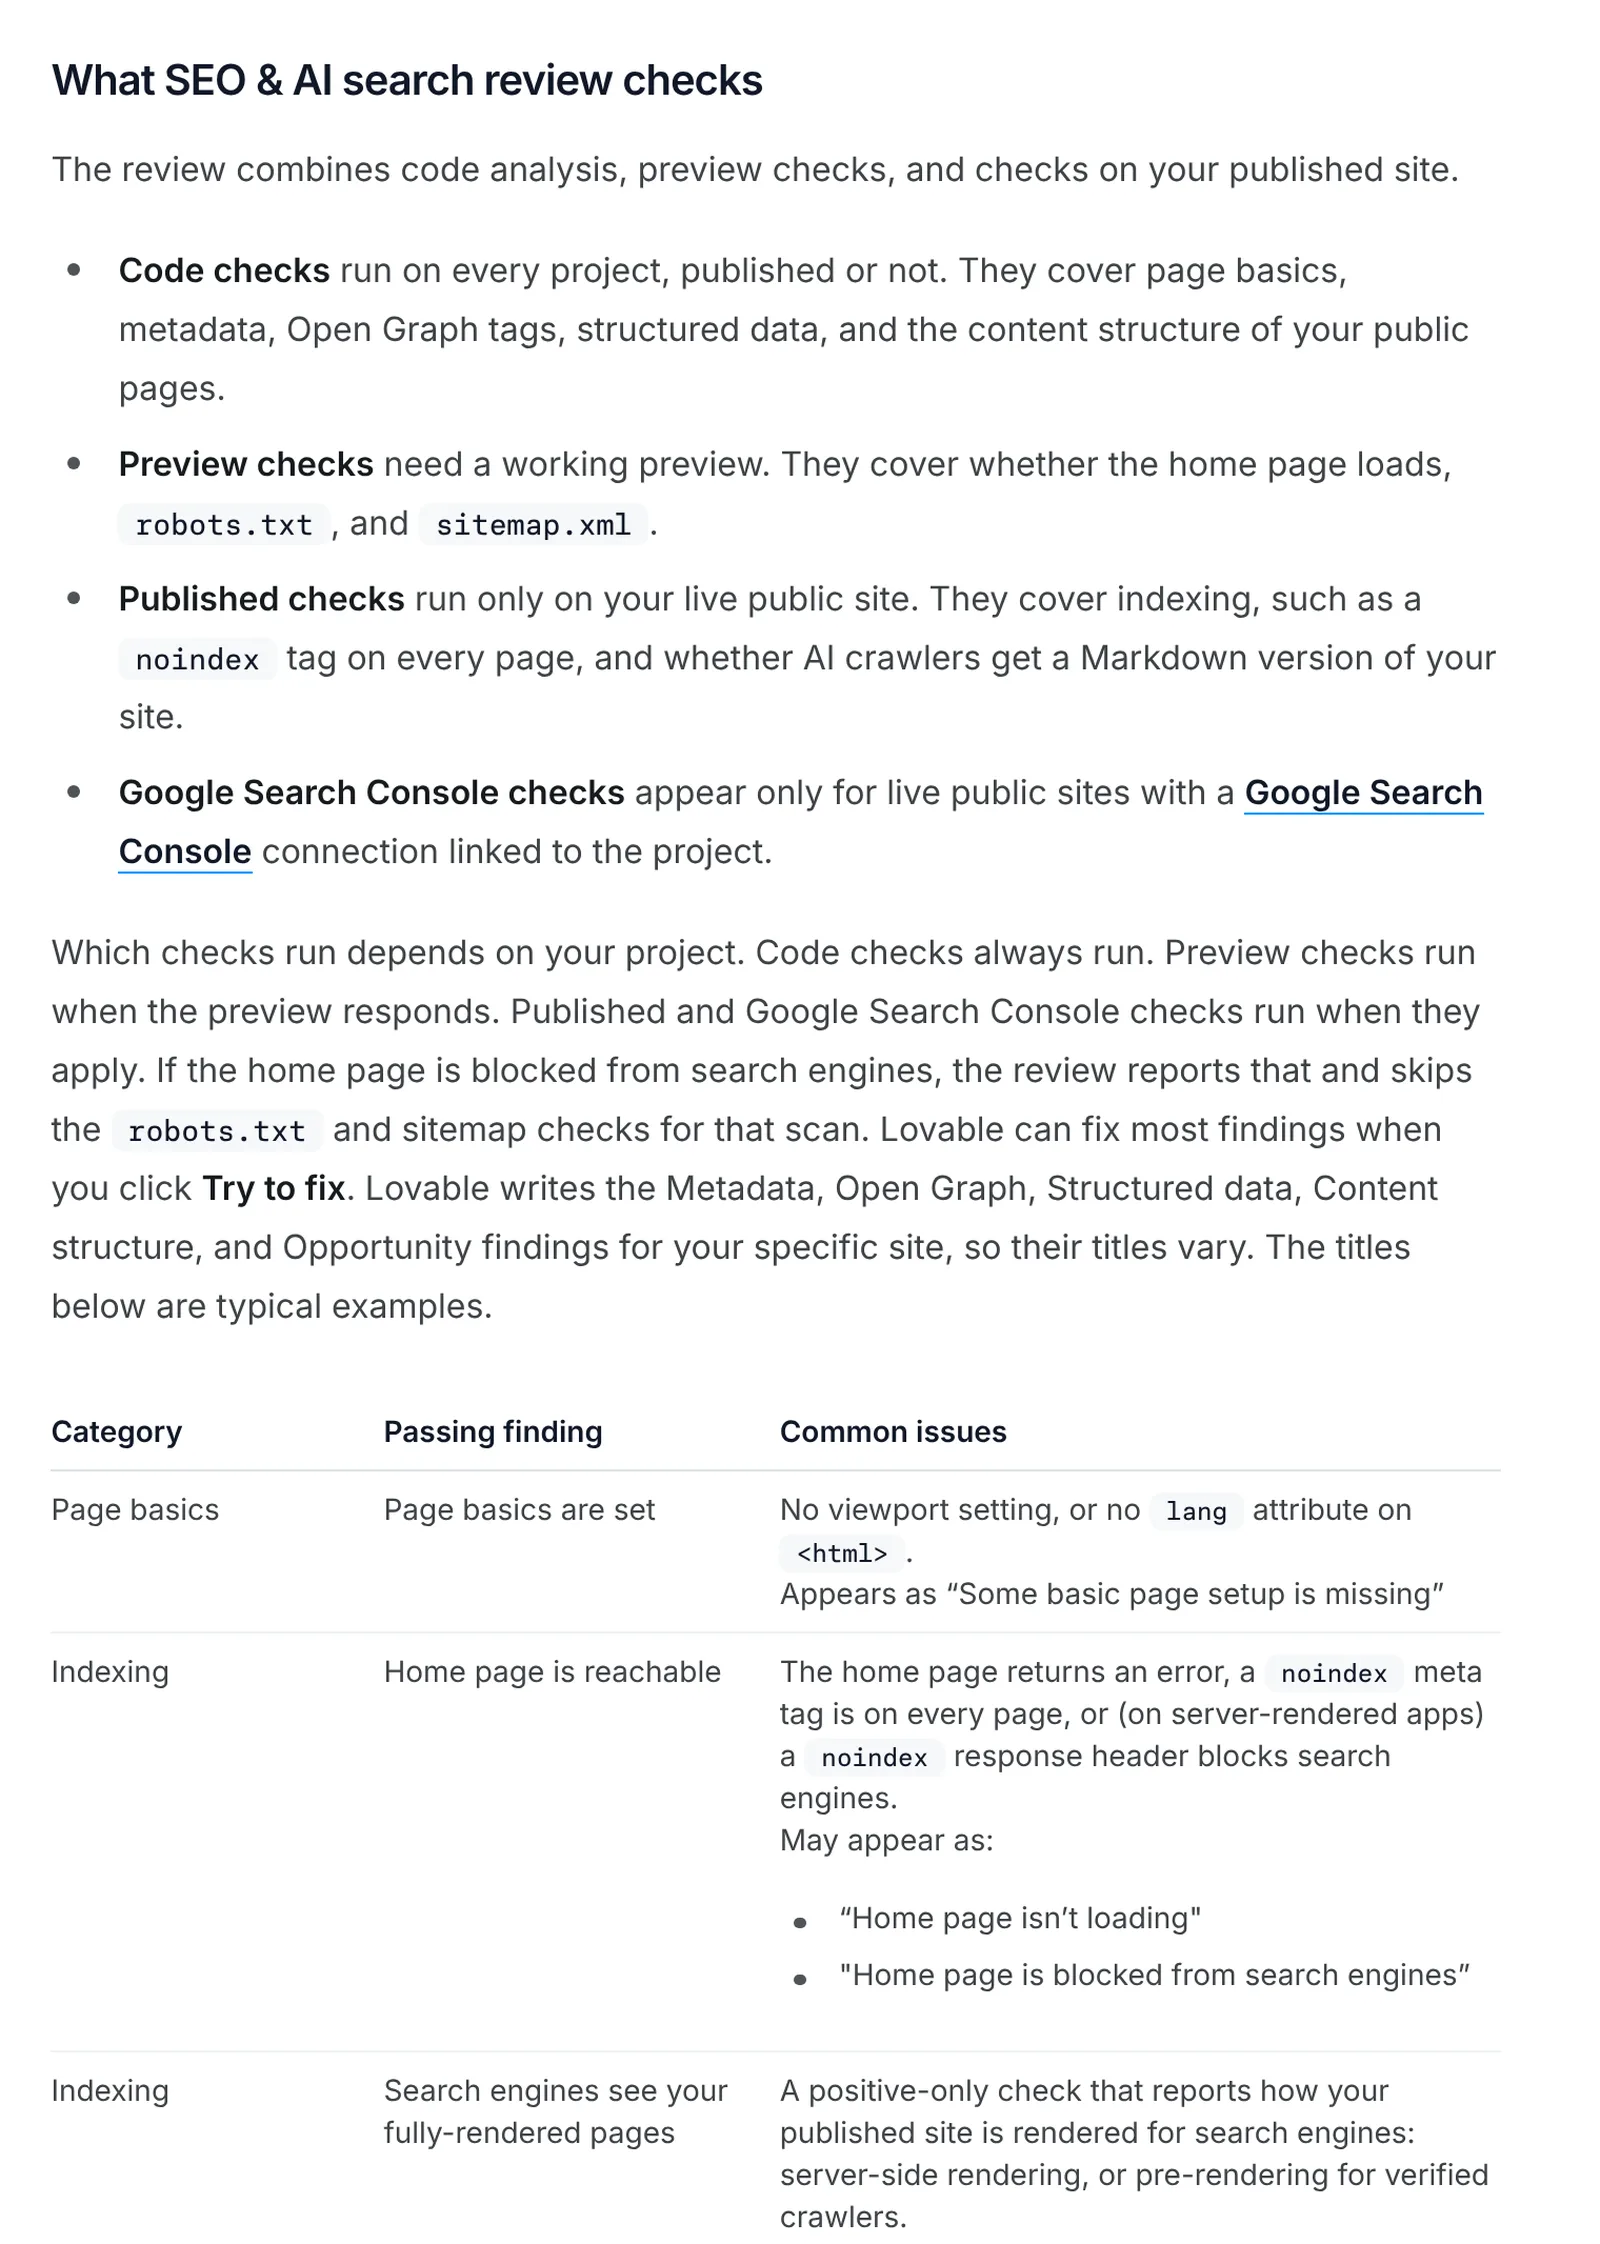
What the review doesn't do, per the same page: it no longer runs Lighthouse, so it reports no page-speed score (Lovable points to PageSpeed Insights instead). It isn't a full accessibility audit. It doesn't judge content quality, search intent, competitor strength, backlinks or whether a topic is worth targeting. And it doesn't treat a missing llms.txt file as a problem, because Lovable doesn't require one.
So run the review first and fix what it finds. Then use the test below to confirm what an outside request actually receives, which the review can only report from Lovable's side.
What the documentation actually states
Lovable's SEO documentation spells out the two rendering behaviours: apps created on or after May 13, 2026 use server-side rendering via TanStack Start, while older React and Vite applications pre-render for verified crawlers and serve the client-side app to everything else.
Read that second behaviour carefully, because it is the one with edges. Pre-rendering for verified crawlers means a crawler that identifies itself and passes verification receives rendered HTML, generated on request. Content that loads with the page is usually included; content that loads late may be missing. Anything unverified (a bot, a link checker, a scraper that doesn't announce itself) receives the regular client-side app. The documentation puts search engines, AI search crawlers such as ChatGPT, Perplexity, Claude and Gemini, social-preview bots and verified SEO tools on the verified side, and says any client asking for Markdown gets a Markdown version on both stacks. That's a documented design choice, not a defect, but it means "it works in Google" and "it works everywhere" are separate questions. Lovable also says it doesn't require llms.txt; if a project already has one, it keeps serving it.
For a broader access check that works on any site, not only Lovable, use our AI visibility audit for business websites.
The audit, in order
This seven-step test runs against your own published URL with tools you already have: a browser's view-source, a command line and a structured-data validator. Replace https://www.example.com/your-page with a real page on your custom domain, and pick a distinctive sentence from its main body copy.
1. Fetch the raw HTML without JavaScript
View source rather than inspecting the DOM. The inspector shows the page after scripts have run, which is exactly what you're trying to exclude. Search the raw response for your sentence. If it's there, the page is server-rendered for you. If the response is a small shell of script tags, the content only exists after JavaScript runs.
2. Repeat it as a plain client
Request the same URL without a browser user agent to see what an unverified client receives:
# 1. As a browser would ask (prints 1 or more if your sentence is in the HTML)
curl -sL -A "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7)" https://www.example.com/your-page | grep -c "your distinctive sentence"

# 2. As an unverified client
curl -sL -A "link-checker/1.0" https://www.example.com/your-page | grep -c "your distinctive sentence"

# 3. Asking for Markdown (header shown is a common convention; Lovable doesn't document the exact mechanism)
curl -sL -H "Accept: text/markdown" https://www.example.com/your-page | head -n 20
How to read the results:
- Both requests find the sentence: the page is server-rendered. That's what a Lovable app created on or after May 13, 2026 should show.
- Neither finds it: you've hit the pre-rendering boundary of an older app. Faking a crawler's user agent isn't a reliable way past it, because Lovable says it serves the pre-rendered copy only to verified crawlers. To see what Google receives, Lovable points to Google's URL Inspection tool in Search Console, or a social platform's link debugger for previews.
- The third request returns Markdown: that's the version Lovable says AI assistants read. If it returns HTML, the request wasn't recognised as a Markdown request, which tells you nothing either way.
Test with the consumers your business actually depends on rather than assuming either list. If you also publish an llms.txt file, our llms.txt example and validation guide shows how to check it, though Lovable doesn't require one.
3. Check one title and description per URL
Confirm that each page has its own title and meta description rather than one set inherited across the whole app. Lovable's documentation says a new project's starting metadata is generic, and its review flags duplicate titles, placeholder text and canonicals that point to the homepage. Check each important route, not only the home page.
4. Confirm one H1 and a real heading order
One H1 per page, and H2s that describe sections rather than being chosen for size. This is the cheapest structural check available, and it's wrong surprisingly often on generated pages.
5. Validate structured data against the server response
Google says it can process structured data that JavaScript adds to the page, as long as it's in the rendered page when Google renders it. Crawlers and tools that don't run JavaScript, which include many AI crawlers, won't see it. So check that the JSON-LD is in the raw response from step 1, and that what it says matches the visible page. Google's structured data guidelines require markup to reflect content readers can see.
6. Read robots.txt and the sitemap as a stranger
Fetch both at their canonical paths. Lovable creates a robots.txt with every new project, but not always a sitemap, so check that /sitemap.xml exists. Confirm it lists the URLs you want indexed with absolute URLs on your own domain, that they return 200 rather than redirecting, and that robots.txt doesn't disallow a path that now holds real content. A template copied from an older project is the usual culprit. To write crawler rules deliberately, see our robots.txt examples for search and AI crawlers, or draft a file with the robots.txt generator.
7. Check canonicals and redirects
Each URL should declare itself canonical unless it's deliberately a duplicate. Then confirm the trailing-slash and non-canonical variants resolve with a single permanent redirect rather than a chain. For the rest of the launch-day checks, see our SEO launch plan for a new website.
Custom domains and indexing
A Lovable app builds search presence on a custom domain, and custom domains are on paid plans (Pro, Business and Enterprise) as of November 6, 2026, not on Free. Lovable's documentation says only publicly published apps can appear in search. Unpublished projects, projects with restricted access and branded workspace URLs (https://{app-name}.{workspace-subdomain}.lovable.app) never do.
- One primary domain. Lovable lets you connect several domains and choose one primary; the others redirect to it, which keeps canonicals and backlinks on one address.
- After you connect it: run the review again, verify the new domain in Google Search Console and submit the sitemap again, so Google indexes the right address. Do the same if you change domains later.
- When a lovable.app address is enough: Lovable suggests it for MVPs, demos, temporary landing pages, internal tools and projects that get their traffic from social or paid channels.
Indexing still takes time. Lovable's FAQ says new pages can take days or longer, and recommends submitting the sitemap, using URL Inspection and requesting indexing for priority pages.
Verified from documentation, versus needs a project-level test
Some answers about Lovable SEO come from Lovable's documentation; the rest only come from testing your own project. Keeping the two apart is the point of this guide.
Verified from Lovable's documentation (read November 6, 2026): that apps created on or after May 13, 2026 (June 22, 2026 on Enterprise) use server-side rendering via TanStack Start; that older React and Vite apps pre-render on request for verified crawlers and otherwise serve the client-side app; that the verified list includes search engines, AI search crawlers such as ChatGPT, Perplexity, Claude and Gemini, social-preview bots and verified SEO tools; that any client requesting Markdown receives a Markdown version on both stacks; that older apps can upgrade to TanStack Start; and what the SEO & AI search review checks and doesn't check.
Needs a test on your own project: which stack your app is on; whether late-loading content is missing from its pre-rendered copy; whether your pages carry unique titles and descriptions; whether your structured data is in the raw response; whether your sitemap and robots.txt are correct; whether your canonicals are clean. Lovable's review answers several of these for your project, against criteria Lovable sets. The outside test confirms them from a reader's side.
You'll notice there are no scores here, and no ranking or traffic figures. None were measured. A number invented to make an audit feel authoritative is worse than no number, because it survives being quoted long after anyone remembers it was invented.
What to do with the result
If the test shows a shell where your content should be, the fix is architectural rather than editorial: no amount of keyword work compensates for content that isn't in the response. On an older Lovable app, the first option is Lovable's own upgrade to TanStack Start, which gives every request server-rendered HTML. If steps 1 and 2 disagree and you stay on the older stack, decide deliberately whether being readable only by verified consumers is acceptable for your business. The verified list includes the major search and AI search crawlers, but it's a list Lovable controls, and unverified tools still receive the client-side app. If everything passes, run Lovable's review regularly and keep improving the content itself.
If you decide the tool itself is the problem, check which Lovable alternatives document how they render. Base44, for example, serves crawlers a saved prerendered copy on custom domains; our Lovable and Base44 comparison sets out how each renders. If Replit is on your list, we also compare how Replit and Lovable host and export apps.
And if what you need is a business website that has to earn search and AI-search traffic, rather than an app, a different kind of tool may fit better. We make PolyDraft, an AI-native website marketing system. It builds a multi-page site that renders HTML on the server, deploys it to your own Cloudflare account, and includes titles, descriptions, structured data, canonicals, a sitemap, robots.txt and llms.txt on every plan. Sites built since November 2026 also get a content calendar planned from SEO and GEO data in their admin. Once the site is deployed and the platform's Search Console access is added to your property, its SEO and GEO autopilot finds new keywords, writes and refreshes pages and reports what moved, every week. PolyDraft is the wrong choice if you're building an app with user accounts and backend logic, which is what Lovable is for. See how PolyDraft handles AI visibility for marketing sites.
When to run it again
Run the test again after any change to how pages are built or served, because rendering behaviour is a property of the build rather than of the account. An upgrade to TanStack Start, a migration between app generations, or a change in how a page fetches its data can all move a route from server-rendered to client-only, or back, without anything in the interface announcing it. Repeat it after any framework or platform upgrade, after adding a route that loads its content differently from the rest, after connecting or changing a domain, and before any launch that matters commercially. Lovable's own suggested baseline is a review monthly and a deeper one quarterly. If an upgrade also changes URLs, templates or copy, the redesign SEO checklist covers the baseline, staging tests and monitoring for that larger change.
Record the date you ran it alongside the result. An audit without a date is indistinguishable from a guess six months later, and the whole point of testing your own project rather than reading a vendor page is that you end up holding evidence rather than an impression.
Frequently asked questions
Is Lovable good for SEO?
Yes, if your pages reach crawlers as HTML, which Lovable's documentation says they do as of November 2026. Apps created on or after May 13, 2026 (June 22 on Enterprise) are server-rendered for everyone. Older React and Vite apps are pre-rendered for verified crawlers, including search engines and AI search crawlers, and serve the client-side app to unverified tools. Run Lovable's SEO & AI search review, then the outside test above on your own URL.
Does Lovable have built-in SEO tools?
Yes. The SEO & AI tab in Analytics has an SEO & AI search review that checks the sitemap, robots.txt, metadata, structured data, content structure, canonicals, indexing and AI readiness, and can fix most findings. Lovable can also connect Google Search Console, verify your site and submit the sitemap, and answer keyword questions with Semrush data. It doesn't measure page speed.
Do I need a pre-rendering service for Lovable?
No, according to Lovable. Its documentation says Lovable-hosted projects don't need an external pre-rendering service for search engines or AI crawlers: newer apps are server-rendered, and older apps get pre-rendering for verified crawlers automatically. If you want every client to receive rendered HTML, upgrade the project to TanStack Start.
Why check without a browser user agent?
Because on an older Lovable app, the response depends on who is asking. A browser runs the app, and a verified crawler receives a pre-rendered copy, while an unverified bot, link checker or SEO scanner receives the client-side app. Which consumers count as verified is a list Lovable controls. Comparing the two requests is what makes that boundary visible.
Do I need paid tools for this audit?
No. View source, a command-line fetch and a structured-data validator cover all seven checks, and Lovable's review is included on every plan. Google Search Console is free. A custom domain, which you need to build search presence, requires a paid Lovable plan.
Does structured data still count if it is added by JavaScript?
For Google, it can: Google says it processes structured data that's in the page when it renders it. Crawlers and tools that don't run JavaScript won't see it, so put JSON-LD in the server response when you can, and make sure it describes what a visitor can actually see.
Written by Vincent Chen, who is accountable for the claims on this page.
About this article. Drafted by an AI agent following PolyDraft's blog workflow, checked by an automated QA script, fact-checked by a separate AI agent, and approved by Vincent Chen. We make PolyDraft, which builds marketing websites rather than apps. Every statement about Lovable comes from Lovable's own documentation, read on November 6, 2026; Google's guidance was checked through search excerpts of Google's documentation, because Google's pages didn't load in our environment. Screenshots of Lovable's public documentation were captured on November 6, 2026; we didn't sign in, build test projects or run the test on a Lovable app for this article. The curl commands are a template to run on your own URL, not results we measured.
Sources
All sources checked November 6, 2026.
- Lovable documentation — SEO and AEO (rendering stacks and dates, verified crawlers, Markdown, the SEO & AI search review, Search Console, Semrush research, custom domains, llms.txt)
- Lovable documentation — Upgrade a project to TanStack Start (default dates, credit cost, publish behaviour)
- Lovable documentation — How Lovable hosts your app (third-party SEO scanners aren't verified crawlers)
- Lovable documentation — Google Search Console connector
- Lovable documentation — Subscription plans (custom domains by plan)
- Google Search Central — Generate structured data with JavaScript (checked through search excerpts)
- Google Search Central — General structured data guidelines (checked through search excerpts)
- Google Search Central — SEO Starter Guide
- Google Search Central — Structured data markup
- Google Search Central — robots.txt introduction
- PolyDraft: Plans, Features
Revision history: November 6, 2026: corrected the publication date to October 8, 2026, when it first went live. October 27, 2026: re-checked against Lovable's documentation and noted that older apps' pre-rendered pages also go to AI search crawlers, social-preview bots and SEO tools.